The Exa connector lets your AI agent act in each user's Exa account. Each user connects their own Exa API key once, and Scalekit sends it with every call, so your agent never handles credentials. It comes with 21 tools.
- Tools
- 21
- What they doRead · write · destructive
- 12 · 8 · 112 read8 write1 destructive
- Users sign in with
- API key
What you can do
- Search the web: run semantic or keyword searches filtered by domain, date range, and content category
- Get cited answers: answer questions with a synthesized response and citations to the source pages
- Read web pages: crawl pages by URL to get their full text, highlights, and summaries
- Find similar pages: discover pages, articles, and companies similar to a given URL
- Run deep research: start research tasks that read many sources and return a single well-cited answer
- Build and monitor websets: collect large sets of matching URLs, enrich each item, and refresh them on a schedule
Setup
Install the SDK
Terminal window npm install @scalekit-sdk/node dotenvTerminal window pip install scalekit-sdk-python python-dotenvSet your credentials
Add your Scalekit credentials to your
.envfile. Find values in app.scalekit.com > Developers > API Credentials..env SCALEKIT_ENVIRONMENT_URL=<your-environment-url>SCALEKIT_CLIENT_ID=<your-client-id>SCALEKIT_CLIENT_SECRET=<your-client-secret>Create the Exa connection
In AgentKit > Connections, create an Exa connection. The name you give it is the
connection_nameyour code passes. See Configure connections.Console steps with screenshots
Register your Exa API key with Scalekit so it can authenticate and proxy requests on behalf of your users. Exa uses API key authentication.
-
Generate an Exa API key
-
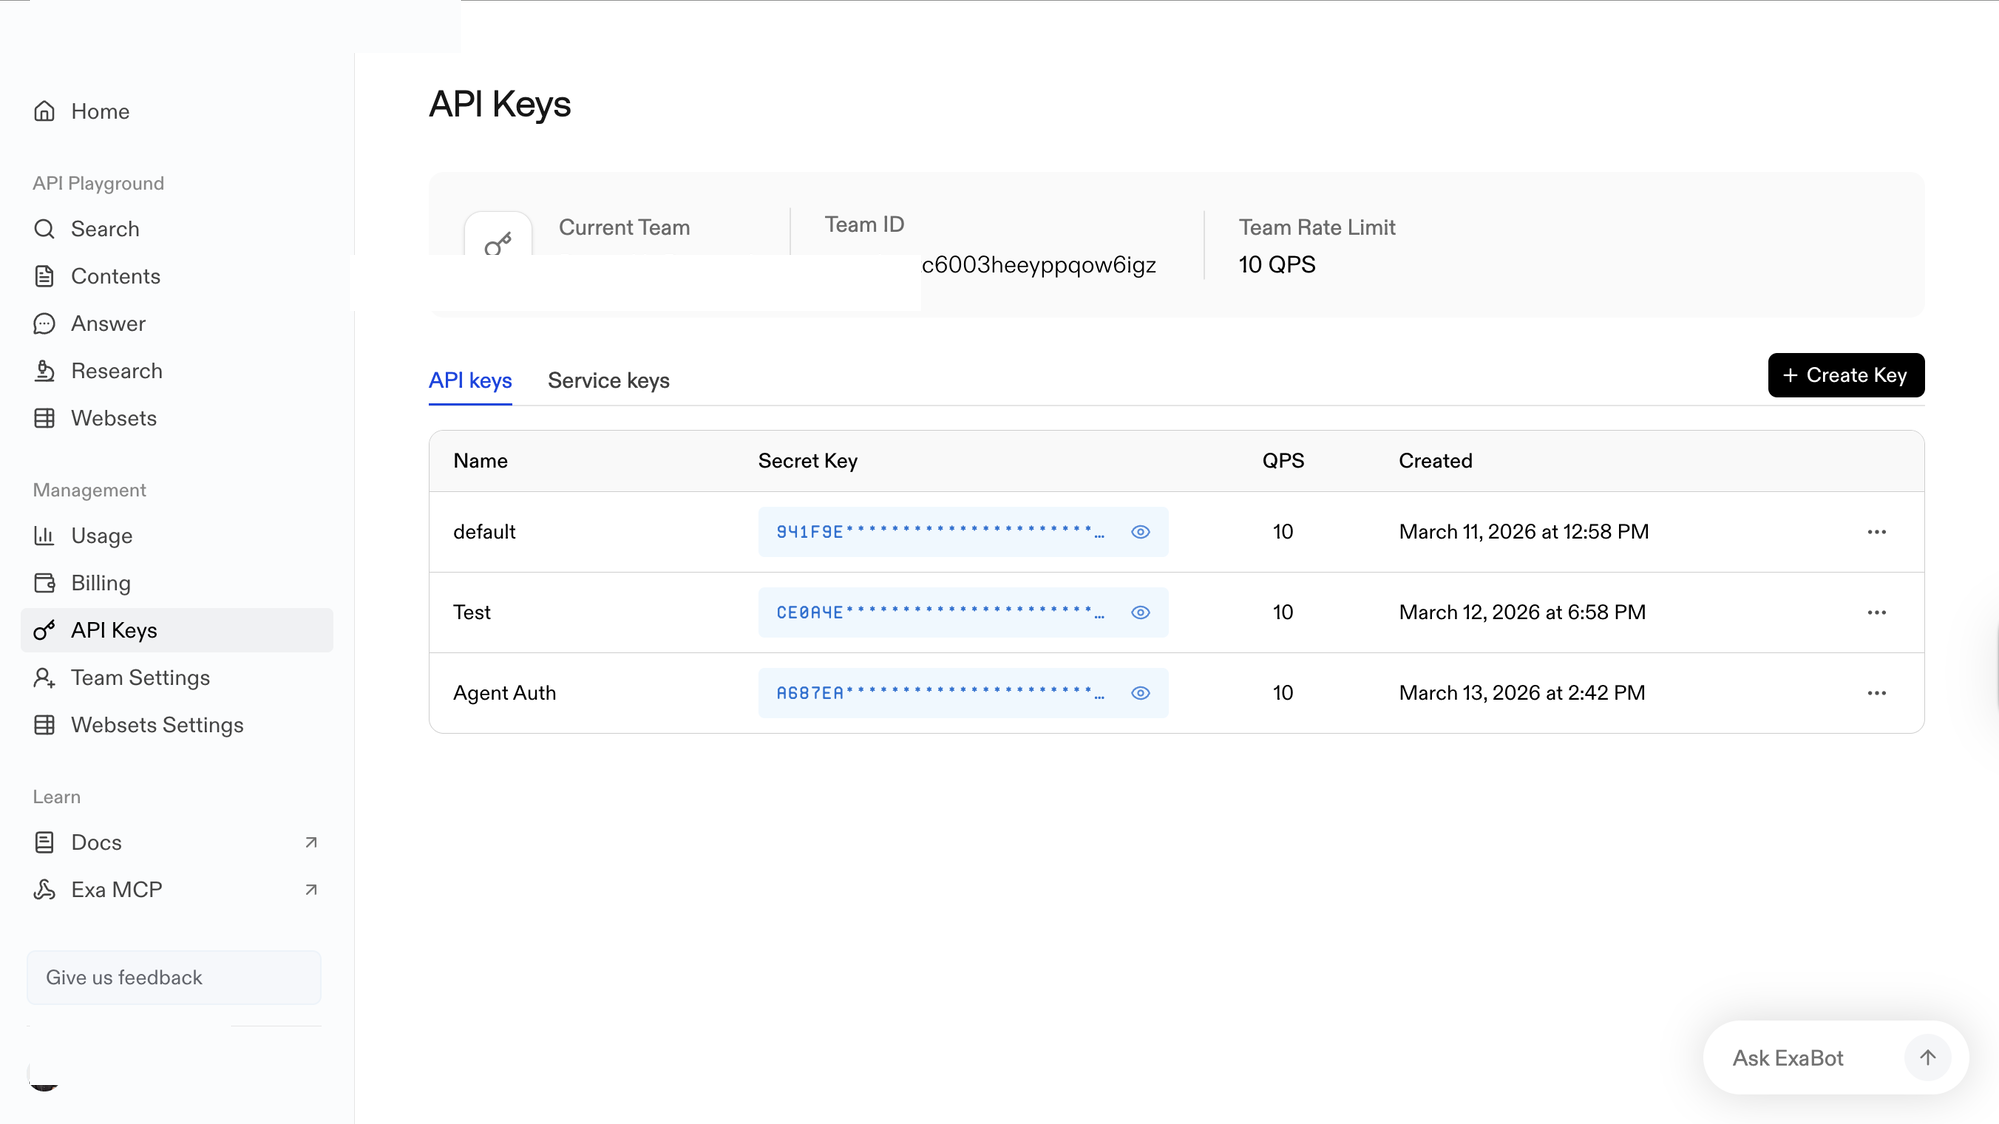
Sign in to dashboard.exa.ai/api-keys. Under Management, click API Keys.
-
Click + Create Key, enter a name (e.g.,
Agent Auth), and confirm. -
In the Secret Key column, click the eye icon to reveal the key and copy it. Store it somewhere safe — you will not be able to view it again.
-
-
Create a connection in Scalekit
-
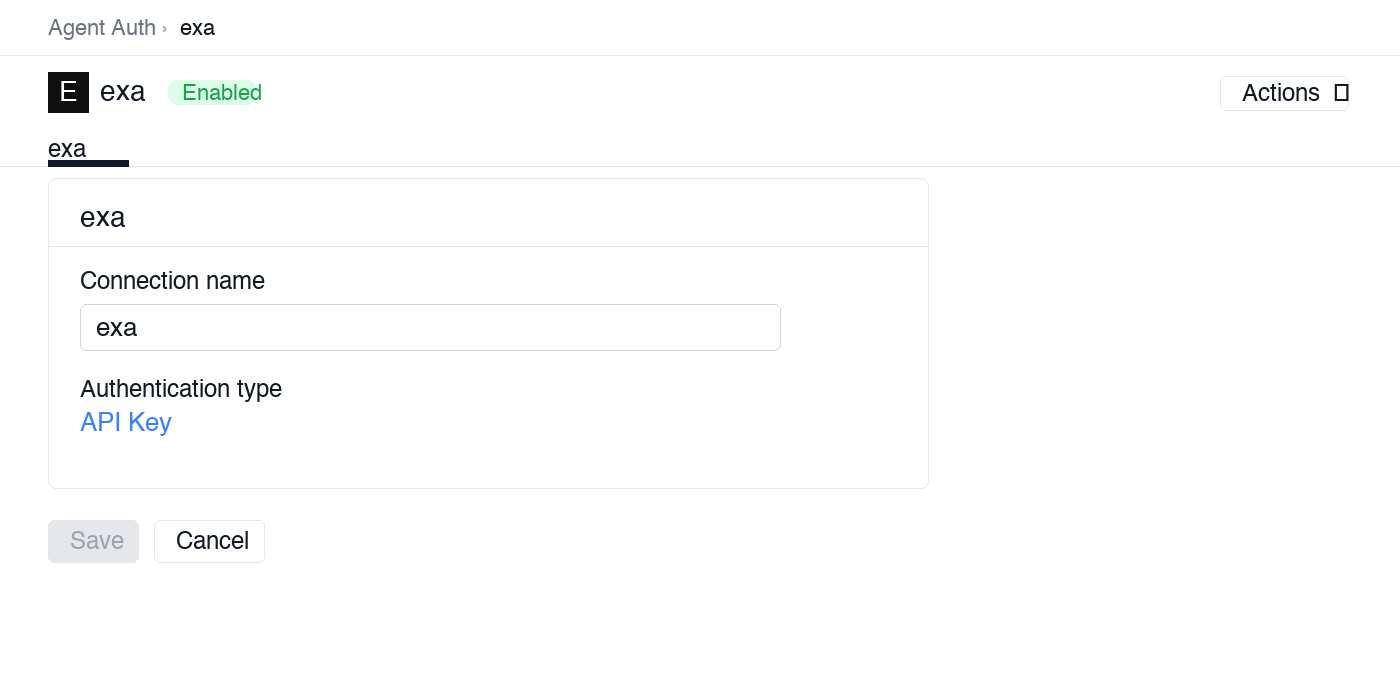
In Scalekit dashboard, go to AgentKit > Connections > Create Connection. Find Exa and click Create.
-
Note the Connection name — you will use this as
connection_namein your code (e.g.,exa).
-
-
Add a connected account
Connected accounts link a specific user identifier in your system to an Exa API key. Add one in the dashboard to test. In production, each user adds their own through the authorization link: they enter their credentials on the page it opens.
In the dashboard, to test
-
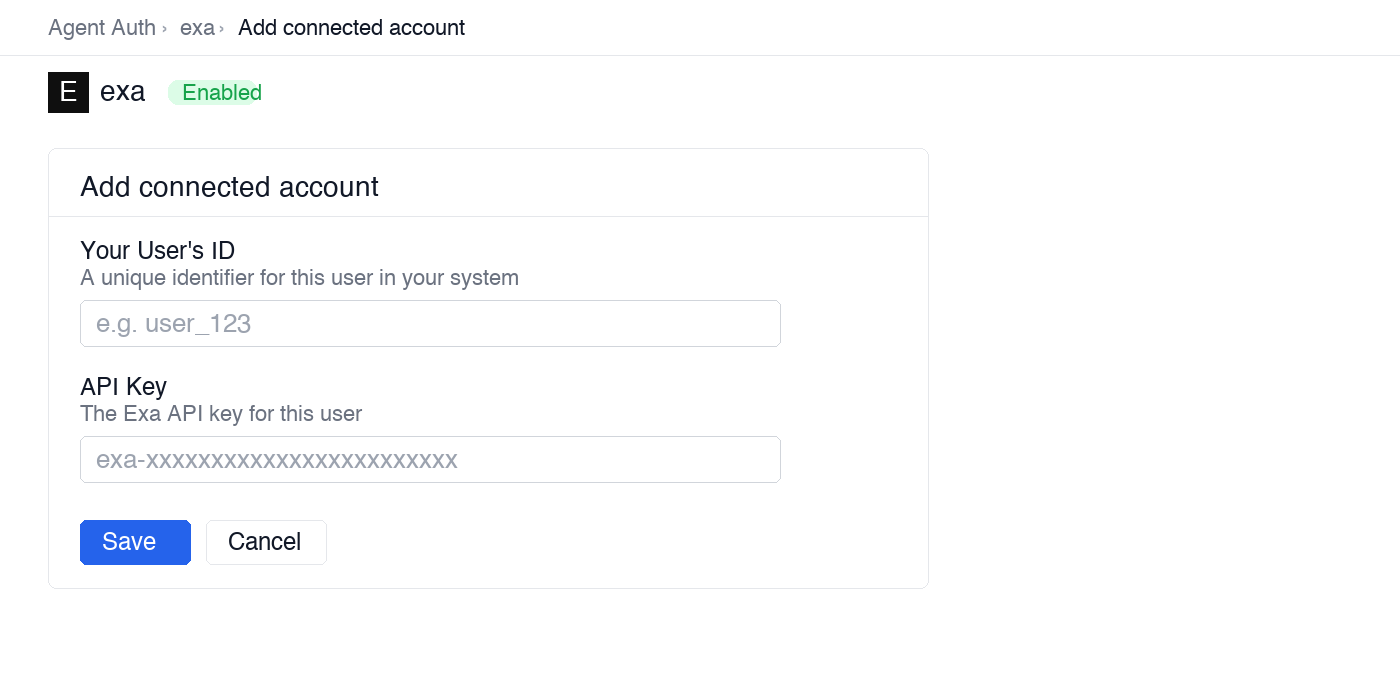
Open the connection you created and click the Connected Accounts tab → Add account.
-
Fill in:
- Your User’s ID — a unique identifier for this user in your system (e.g.,
user_123) - API Key — the Exa API key you copied in step 1
- Your User’s ID — a unique identifier for this user in your system (e.g.,
-
Click Save.
From your backend, if your app already has the credentials
For example, when users enter them on a settings page in your app:
import { ConnectorStatus } from '@scalekit-sdk/node'const authorizationDetails = {details: {case: 'staticAuth',value: { details: { api_key: 'your-exa-api-key' } },},};let { connectedAccount } = await scalekit.actions.upsertConnectedAccount({connectionName: 'exa',identifier: 'user_123',authorizationDetails,});// Make sure the account is ACTIVE before the first tool call.if (connectedAccount?.status !== ConnectorStatus.ACTIVE) {({ connectedAccount } = await scalekit.actions.upsertConnectedAccount({connectionName: 'exa',identifier: 'user_123',authorizationDetails,}));}authorization_details = {"static_auth": {"api_key": "your-exa-api-key"}}response = scalekit_client.actions.upsert_connected_account(connection_name="exa",identifier="user_123",authorization_details=authorization_details,)# Make sure the account is ACTIVE before the first tool call.if response.connected_account.status != "ACTIVE":response = scalekit_client.actions.upsert_connected_account(connection_name="exa",identifier="user_123",authorization_details=authorization_details,) -
-
Authorize a user and make your first call
quickstart.mts import { ScalekitClient } from '@scalekit-sdk/node'import 'dotenv/config'import { createInterface } from 'node:readline/promises'const scalekit = new ScalekitClient(process.env.SCALEKIT_ENVIRONMENT_URL,process.env.SCALEKIT_CLIENT_ID,process.env.SCALEKIT_CLIENT_SECRET,)const actions = scalekit.actionsconst connector = 'exa'const identifier = 'user_123'// Generate an authorization link for the userconst { link } = await actions.getAuthorizationLink({ connectionName: connector, identifier })console.log('Authorize Exa:', link)const rl = createInterface({ input: process.stdin, output: process.stdout })await rl.question('Press Enter after authorizing...')rl.close()// Make your first callconst result = await actions.executeTool({connector,identifier,toolName: 'exa_list_webset_monitors',toolInput: {},})console.log(result)Terminal window npx tsx quickstart.mtsquickstart.py import osfrom scalekit import ScalekitClientfrom dotenv import load_dotenvload_dotenv()scalekit_client = ScalekitClient(env_url=os.getenv("SCALEKIT_ENVIRONMENT_URL"),client_id=os.getenv("SCALEKIT_CLIENT_ID"),client_secret=os.getenv("SCALEKIT_CLIENT_SECRET"),)actions = scalekit_client.actionsconnection_name = "exa"identifier = "user_123"# Generate an authorization link for the userlink_response = actions.get_authorization_link(connection_name=connection_name,identifier=identifier,)print("Authorize Exa:", link_response.link)input("Press Enter after authorizing...")# Make your first callresult = actions.execute_tool(tool_input={},tool_name="exa_list_webset_monitors",connection_name=connection_name,identifier=identifier,)print(result)Terminal window python quickstart.pyEach user opens the link once and enters their Exa credentials there. If your app already has a user's credentials, add the account from your backend instead, as the console steps above show. See Authorize a user for the full flow and statuses.
Tools
Pass the exact name toexecute_toolexa_answerGet a natural language answer to a question by searching the web with Exa and synthesizing results.Read-onlyGet Answer
Get a natural language answer to a question by searching the web with Exa and synthesizing results. Returns a direct answer with citations to the source pages. Ideal for factual questions, current events, and research queries. Rate limit: 60 requests/minute.
Inputs
querystringrequired- The question or query to answer from web sources.
exclude_domainsarray- JSON array of domains to exclude from answer sources.
include_domainsarray- JSON array of domains to restrict source search to. Example: ["reuters.com","bbc.com"]
include_textboolean- When true, also returns the source page text alongside the synthesized answer.
num_resultsinteger- Number of web sources to use when generating the answer (1–20). More sources improves accuracy but costs more credits.
exa_crawlCrawl one or more web pages by URL and extract their content including full text, highlights, and AI-generated summaries.Read-onlyCrawl Pages
Crawl one or more web pages by URL and extract their content including full text, highlights, and AI-generated summaries. Useful for reading specific pages discovered via search. Rate limit: 60 requests/minute. Credit consumption depends on number of URLs.
Inputs
urlsarrayrequired- JSON array of URLs to crawl and extract content from.
highlights_per_urlinteger- Number of highlight sentences to return per URL when include_highlights is true. Defaults to 3.
include_highlightsboolean- When true, returns the most relevant sentence-level highlights from each page.
include_html_tagsboolean- When true, retains HTML tags in the extracted text. Defaults to false (plain text only).
include_summaryboolean- When true, returns an AI-generated summary for each crawled page.
max_charactersinteger- Maximum characters of text to extract per page. Defaults to 5000.
summary_querystring- Optional query to focus the AI summary on a specific aspect of the page.
exa_find_similarFind web pages similar to a given URL using Exa's neural similarity search.Read-onlyFind Similar Pages
Find web pages similar to a given URL using Exa's neural similarity search. Useful for competitor research, finding related articles, or discovering similar companies. Optionally returns page text, highlights, or summaries. Rate limit: 60 requests/minute.
Inputs
urlstringrequired- The URL to find similar pages for.
end_published_datestring- Only return pages published before this date. ISO 8601 format: YYYY-MM-DDTHH:MM:SS.000Z
exclude_domainsarray- Array of domains to exclude from results.
include_domainsarray- Array of domains to restrict results to.
include_textboolean- When true, returns the full text content of each result page.
max_charactersinteger- Maximum characters of page text to return per result when include_text is true. Defaults to 3000.
num_resultsinteger- Number of similar results to return (1–100). Defaults to 10.
start_published_datestring- Only return pages published after this date. ISO 8601 format: YYYY-MM-DDTHH:MM:SS.000Z
exa_get_research_taskCheck the status of a Research Task and retrieve its output once complete.Read-onlyGet Research Task
Check the status of a Research Task and retrieve its output once complete. Use the task ID returned by Create Research Task.
Inputs
task_idstringrequired- The ID of the research task to retrieve.
exa_get_websetGet the status and details of an existing Exa Webset by its ID.Read-onlyGet Webset
Get the status and details of an existing Exa Webset by its ID. Use this to poll the status of an async webset created with Create Webset. Returns metadata including status (created, running, completed, cancelled), progress, and configuration.
Inputs
webset_idstringrequired- The ID of the webset to retrieve.
exa_get_webset_itemRetrieve a single item from an Exa Webset by its item ID, including its full enrichment data and verification evidence.Read-onlyGet Webset Item
Retrieve a single item from an Exa Webset by its item ID, including its full enrichment data and verification evidence. Use List Webset Items to find item IDs.
Inputs
item_idstringrequired- The ID of the item to retrieve.
webset_idstringrequired- The ID of the webset that contains the item.
exa_get_webset_monitorGet a single Monitor's configuration, enabled/disabled status, cadence, and last/next run details.Read-onlyGet Webset Monitor
Get a single Monitor's configuration, enabled/disabled status, cadence, and last/next run details.
Inputs
monitor_idstringrequired- The ID of the monitor to retrieve.
exa_list_webset_itemsList the collected URLs and items from a completed Exa Webset.Read-onlyList Webset Items
List the collected URLs and items from a completed Exa Webset. Use this after polling Get Webset until its status is 'completed' to retrieve the discovered results.
Inputs
webset_idstringrequired- The ID of the webset to retrieve items from.
countinteger- Number of items to return per page. Defaults to 10.
cursorstring- Pagination cursor from a previous response to fetch the next page of items.
exa_list_webset_monitorsList Monitors, which keep a Webset continuously refreshed on a schedule via a cron cadence.Read-onlyList Webset Monitors
List Monitors, which keep a Webset continuously refreshed on a schedule via a cron cadence. The entire Monitors resource is uncovered.
Inputs
cursorstring- Pagination cursor from a previous response to fetch the next page.
limitinteger- The number of monitors to return per page. Defaults to 25.default
25 webset_idstring- Filter to monitors belonging to this webset only.
exa_list_websetsList all Exa Websets in your account with optional pagination.Read-onlyList Websets
List all Exa Websets in your account with optional pagination. Returns a list of websets with their IDs, statuses, and configurations.
Inputs
countinteger- Number of websets to return per page. Defaults to 10.
cursorstring- Pagination cursor from a previous response to fetch the next page.
exa_researchRun in-depth research on a topic using Exa's neural search.Read-onlyResearch Topic
Run in-depth research on a topic using Exa's neural search. Performs a semantic search and returns results with full page text and AI-generated summaries, providing structured multi-source research output. Best for comprehensive topic analysis. Rate limit: 60 requests/minute.
Inputs
querystringrequired- The research topic or question to investigate across the web.
categorystring- Restrict research to a specific content category for more targeted results.one of
companyresearch papernewsgithubtweetmoviesongpersonal sitepdf exclude_domainsarray- JSON array of domains to exclude from research results.
include_domainsarray- JSON array of domains to restrict research sources to. Useful to focus on authoritative sources.
max_charactersinteger- Maximum characters of text to extract per source page. Defaults to 5000.
num_resultsinteger- Number of sources to gather for the research (1–20). More sources provide broader coverage.
start_published_datestring- Only include sources published after this date. ISO 8601 format.
summary_querystring- Optional focused question to guide the AI page summaries. Defaults to the main research query.
exa_searchSearch the web using Exa's AI-powered semantic or keyword search engine.Read-onlySearch Web
Search the web using Exa's AI-powered semantic or keyword search engine. Supports filtering by domain, date range, content category, and result type. Optionally returns page text, highlights, or summaries alongside search results. Rate limit: 60 requests/minute.
Inputs
querystringrequired- The search query. For neural/auto type, natural language works best. For keyword type, use specific terms.
categorystring- Restrict results to a specific content category.one of
companyresearch papernewspersonal sitefinancial reportpeople end_crawl_datestring- Only return pages crawled (discovered) before this date. ISO 8601 format.
end_published_datestring- Only return pages published before this date. ISO 8601 format: YYYY-MM-DDTHH:MM:SS.000Z
exclude_domainsarray- JSON array of domains to exclude from results. Example: ["reddit.com","quora.com"]
include_domainsarray- JSON array of domains to restrict results to. Example: ["techcrunch.com","wired.com"]
include_highlightsboolean- When true, returns relevant text snippets from each result page.
include_summaryboolean- When true, returns an LLM-generated summary for each result page.
include_textboolean- When true, returns the full text content of each result page (up to max_characters).
max_age_hoursinteger- Maximum age of cached content in hours. 0 fetches fresh content; -1 always uses cache; omit for fallback. Max 720.
max_charactersinteger- Maximum characters of page text to return per result when include_text is true. Defaults to 3000.
moderationboolean- When true, enables content moderation to filter unsafe content from results.
num_resultsinteger- Number of results to return (1–100). Defaults to 10.
start_crawl_datestring- Only return pages crawled (discovered) after this date. ISO 8601 format.
start_published_datestring- Only return pages published after this date. ISO 8601 format: YYYY-MM-DDTHH:MM:SS.000Z
system_promptstring- Additional instructions that guide generated output, source preferences, or agent behavior.
typestring- Search type: 'neural' for semantic AI search (best for natural language), 'keyword' for exact-match keyword search, 'auto' to let Exa decide.one of
autoinstantfastdeep-litedeepdeep-reasoning use_autopromptboolean- When true, Exa automatically rewrites the query to be more semantically effective.
user_locationstring- Two-letter ISO country code of the user, used to localize results. e.g. US, GB, DE.
exa_cancel_websetCancel a running Exa Webset so it stops discovering new items.WriteCancel Webset
Cancel a running Exa Webset so it stops discovering new items. Already-collected items are preserved and remain accessible via List Webset Items.
- Idempotent
Inputs
webset_idstringrequired- The ID of the webset to cancel.
exa_cancel_webset_enrichmentCancel a running enrichment on a webset, stopping further per-item research.WriteCancel Webset Enrichment
Cancel a running enrichment on a webset, stopping further per-item research. Already-populated values are kept; a cancelled enrichment cannot be resumed. Existing tools can only create an enrichment, never cancel one.
- Idempotent
Inputs
enrichment_idstringrequired- The ID of the enrichment to cancel.
webset_idstringrequired- The ID of the webset the enrichment belongs to.
exa_create_research_taskStart an asynchronous deep-research task: Exa autonomously searches, reads, and synthesizes many web sources into a single well-cited answer, optionally shaped by a JSON output schema.WriteCreate Research Task
Start an asynchronous deep-research task: Exa autonomously searches, reads, and synthesizes many web sources into a single well-cited answer, optionally shaped by a JSON output schema. Returns a task ID — poll Get Research Task with it until the task completes. Slower and more thorough than Research Topic. High credit consumption.
Inputs
instructionsstringrequired- The research goal or question for Exa to investigate autonomously across the web.
modelstring- Which Exa research model to use.one of
exa-researchexa-research-pro output_schemaobject- JSON schema describing the exact shape of the structured output you want back, instead of free-form text.
exa_create_webset_enrichmentAdd an AI enrichment to an Exa Webset that derives an extra structured field for every item (e.g.WriteCreate Webset Enrichment
Add an AI enrichment to an Exa Webset that derives an extra structured field for every item (e.g. company employee count, contact email). Exa researches each existing and future item to fill in the field. Additional credit consumption per item.
Inputs
descriptionstringrequired- Natural-language description of the data point to derive for every item.
webset_idstringrequired- The ID of the webset to enrich.
formatstring- Expected data type of the enrichment result.one of
textdatenumberoptionsemailphone optionsarray- JSON array of allowed option labels, required when format is 'options'.
exa_create_webset_monitorCreate a Monitor with a cron cadence and a search-or-refresh behavior for an existing Webset, so it keeps discovering new matching items (or re-verifying existing ones) on a schedule without manual reruns.WriteCreate Webset Monitor
Create a Monitor with a cron cadence and a search-or-refresh behavior for an existing Webset, so it keeps discovering new matching items (or re-verifying existing ones) on a schedule without manual reruns.
Inputs
behavior_typestringrequired- What the monitor does each run: 'search' to discover new items with a fresh search, or 'refresh' to re-verify/update existing items.one of
searchrefresh cronstringrequired- Cron expression controlling how often the monitor runs, e.g. '0 9 * * 1' for every Monday at 9am.
timezonestringrequired- IANA timezone the cron expression is evaluated in.
webset_idstringrequired- The ID of the webset this monitor keeps refreshed.
search_behaviorstring- When behavior_type is 'search', whether new results are 'append'ed to the webset or 'override' its items.one of
appendoverridedefaultappend search_countinteger- When behavior_type is 'search', the target number of new items to collect per run.default
10 search_querystring- Required when behavior_type is 'search'. The query describing what new items to find on each run.
exa_create_webset_searchRun an additional search against an existing Exa Webset to discover more matching items without creating a brand-new webset.WriteCreate Webset Search
Run an additional search against an existing Exa Webset to discover more matching items without creating a brand-new webset. Useful for broadening or refining an in-progress or completed webset. High credit consumption.
Inputs
querystringrequired- The search query describing what kinds of pages or entities to find. Be specific and descriptive for best results.
webset_idstringrequired- The ID of the webset to add this search to.
countinteger- Target number of additional URLs to collect with this search.
entity_typestring- The type of entity to search for. Helps Exa understand what constitutes a valid result match.one of
companypersonarticleresearch paperjob listingproductrepository exclude_domainsarray- JSON array of domains to exclude from this search's results.
include_domainsarray- JSON array of domains to restrict this search's sources to.
exa_update_websetUpdate an existing Exa Webset's metadata or external reference ID.WriteUpdate Webset
Update an existing Exa Webset's metadata or external reference ID. Use this to tag a webset for your own bookkeeping without recreating it.
- Idempotent
Inputs
webset_idstringrequired- The ID of the webset to update.
external_idstring- New external identifier to tag this webset for reference in your system.
metadataobject- Free-form key-value metadata to attach to the webset. Replaces any existing metadata.
exa_websetsExecute a complex web query designed to discover and return large sets of URLs (up to thousands) matching specific criteria.WriteCreate Webset
Execute a complex web query designed to discover and return large sets of URLs (up to thousands) matching specific criteria. Websets are ideal for lead generation, market research, competitor analysis, and large-scale data collection. Returns a webset ID — poll status with GET /websets/v0/websets/{id}. High credit consumption.
Inputs
querystringrequired- The search query describing what kinds of pages or entities to find. Be specific and descriptive for best results.
countinteger- Target number of URLs to collect. Can range from hundreds to thousands. Higher counts take longer and consume more credits.
entity_typestring- The type of entity to search for. Helps Exa understand what constitutes a valid result match.one of
companypersonarticleresearch paperjob listingproductrepository exclude_domainsarray- JSON array of domains to exclude from webset results.
external_idstring- Optional external identifier to tag this webset for reference in your system.
include_domainsarray- JSON array of domains to restrict webset sources to.
exa_delete_websetDelete an Exa Webset by its ID.DestructiveDelete Webset
Delete an Exa Webset by its ID. This permanently removes the webset and all its collected items. This action cannot be undone.
- Idempotent
Inputs
webset_idstringrequired- The ID of the webset to delete.
No tools match.
Workflows
Proxy API call
const result = await actions.request({ connectionName: 'exa', identifier: 'user_123', path: '/search', method: 'POST', body: { query: 'LLM observability tools 2025', num_results: 5 },});console.log(result.data);result = actions.request( connection_name='exa', identifier='user_123', path="/search", method="POST", json={"query": "LLM observability tools 2025", "num_results": 5},)print(result)Semantic search
Search the web by meaning, not just keywords. This example searches for companies in the AI infrastructure space and returns AI-generated summaries for each result.
result = actions.execute_tool( connection_name='exa', identifier='user_123', tool_name="exa_search", tool_input={ "query": "AI infrastructure companies building GPU cloud platforms", "num_results": 10, "type": "neural", "category": "company", "contents": { "summary": {"query": "What does this company do and who are their customers?"} } })
for item in result.data.get("results", []): print(f"{item['title']}: {item['url']}") print(f" → {item.get('summary', 'No summary')}\n")Search with full content enrichment
Retrieve the full page text and highlighted snippets alongside search results — useful when you want to pass source material directly into an LLM context window.
result = actions.execute_tool( connection_name='exa', identifier='user_123', tool_name="exa_search", tool_input={ "query": "OpenAI API rate limits and pricing 2025", "num_results": 5, "type": "keyword", # keyword mode for precise terms "include_domains": ["openai.com", "platform.openai.com"], "contents": { "text": {"max_characters": 2000}, # cap text to save tokens "highlights": { "num_sentences": 3, "highlights_per_url": 2 } } })
for item in result.data.get("results", []): print(f"## {item['title']}") print(f"URL: {item['url']}") if item.get("highlights"): print("Highlights:") for h in item["highlights"]: print(f" - {h}") print()Find similar pages
Discover pages that are semantically similar to a known URL — useful for competitive research, finding alternative data sources, or discovering similar products.
# Find companies similar to a known competitorresult = actions.execute_tool( connection_name='exa', identifier='user_123', tool_name="exa_find_similar", tool_input={ "url": "https://www.linear.app", "num_results": 10, "exclude_domains": ["linear.app"], # exclude the source URL itself "start_published_date": "2024-01-01", # only recently indexed pages "contents": { "summary": {"query": "What product does this company build?"} } })
print("Similar companies to Linear:")for item in result.data.get("results", []): print(f" {item['title']} — {item['url']}") if item.get("summary"): print(f" {item['summary']}")Get content for known URLs
Extract structured content from a list of URLs you already have — from a CRM export, a prior search, or a manually curated list. No search query required.
# Enrich a list of company URLs from your CRMcompany_urls = [ "https://www.anthropic.com", "https://mistral.ai", "https://cohere.com",]
result = actions.execute_tool( connection_name='exa', identifier='user_123', tool_name="exa_crawl", tool_input={ "urls": company_urls, "include_summary": True, "summary_query": "What AI models or products does this company offer, and who are their target customers?", "max_characters": 5000 # cap extracted text per page })
for item in result.data.get("results", []): print(f"{item['url']}: {item.get('summary', 'No summary')}")Get a direct answer
Ask a question and get a synthesized natural language answer grounded in live web sources. Returns the answer and the source URLs used — ready to display or inject into a citation-aware LLM prompt.
result = actions.execute_tool( connection_name='exa', identifier='user_123', tool_name="exa_answer", tool_input={ "query": "What are the context window sizes and pricing for Claude Sonnet and GPT-4o as of 2025?", "num_results": 8, "text": True, # include source snippets "include_domains": ["anthropic.com", "openai.com", "platform.openai.com"] })
print("Answer:", result.data.get("answer"))print("\nSources:")for source in result.data.get("sources", []): print(f" - {source['title']}: {source['url']}")Deep research on a topic
Run multi-angle research that decomposes your topic into parallel sub-queries and synthesizes the results. Use output_schema to get structured JSON instead of free-form text — useful for generating reports your code can consume directly.
result = actions.execute_tool( connection_name='exa', identifier='user_123', tool_name="exa_research", tool_input={ "topic": "Competitive landscape of AI coding assistants in 2025 — key players, pricing, and differentiators", "num_subqueries": 5, "output_schema": { "type": "object", "properties": { "summary": {"type": "string"}, "competitors": { "type": "array", "items": { "type": "object", "properties": { "name": {"type": "string"}, "pricing": {"type": "string"}, "key_differentiator": {"type": "string"}, "target_customer": {"type": "string"} } } }, "market_trends": { "type": "array", "items": {"type": "string"} } }, "required": ["summary", "competitors", "market_trends"] } })
report = result.dataprint("Summary:", report.get("summary"))print("\nCompetitors:")for c in report.get("competitors", []): print(f" {c['name']}: {c.get('key_differentiator')}")print("\nTrends:")for t in report.get("market_trends", []): print(f" - {t}")LangChain integration
Let an LLM decide which Exa tool to call based on natural language. This example builds an agent that can search, retrieve content, and answer research questions on demand.
from langchain_openai import ChatOpenAIfrom langchain.agents import AgentExecutor, create_openai_tools_agentfrom langchain_core.prompts import ( ChatPromptTemplate, SystemMessagePromptTemplate, HumanMessagePromptTemplate, MessagesPlaceholder, PromptTemplate)
# Load all Exa tools in LangChain format. Use page_size=100 so connector tool lists are not truncated.tools = actions.langchain.get_tools( identifier='user_123', providers=["EXA"], page_size=100)
prompt = ChatPromptTemplate.from_messages([ SystemMessagePromptTemplate(prompt=PromptTemplate( input_variables=[], template=( "You are a research assistant with access to Exa web search tools. " "Use exa_search for general queries, exa_answer for direct questions, " "exa_find_similar for competitive analysis, and exa_research for deep multi-source topics. " "Always cite your sources." ) )), MessagesPlaceholder(variable_name="chat_history", optional=True), HumanMessagePromptTemplate(prompt=PromptTemplate( input_variables=["input"], template="{input}" )), MessagesPlaceholder(variable_name="agent_scratchpad")])
llm = ChatOpenAI(model="gpt-4o")agent = create_openai_tools_agent(llm, tools, prompt)agent_executor = AgentExecutor(agent=agent, tools=tools, verbose=True)
result = agent_executor.invoke({ "input": "Who are the top 5 competitors to Notion for team knowledge management? Summarize each and compare their pricing."})print(result["output"])